 Two-Person Hotel Lobby
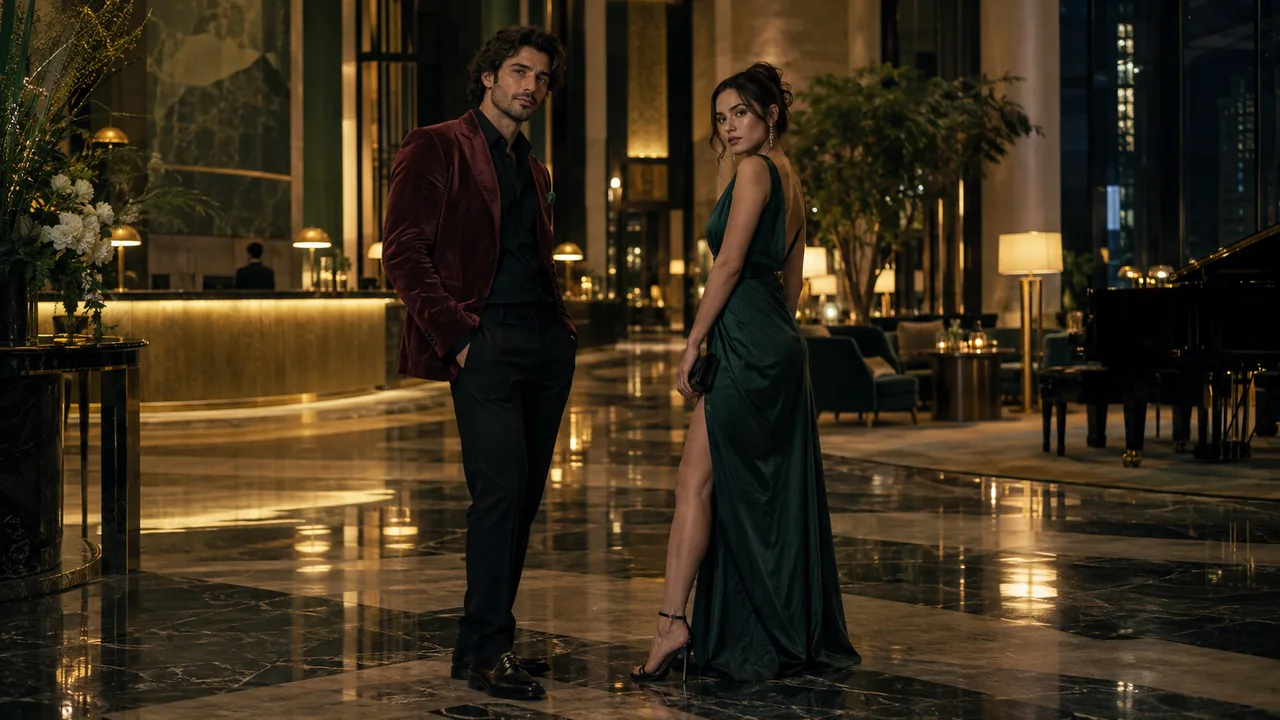
The visual language of this effect
A place with depth
The lobby supplies a broad floor, tall interior lines and reflections. These background cues establish a location without competing with the two faces.
Warm light, dark surroundings
Gold practical lighting and deeper green shadows define the intended palette. Skin should remain readable instead of being swallowed by the darker interior.
A paired performance
The intended camera language moves from a shared view toward individual attention. Small head and shoulder movements suit a short clip better than a complex dance request.
The intended scene progression
These beats describe the recipe’s direction. They are not guaranteed cuts, exact camera paths or fixed timestamps in a generated result.
Establish the pair
Read the scene as a shared medium or wider view. The lobby should be recognizable while both people remain the main subject.
Bring attention closer
The intended approach and changes of framing give the pair individual presence. Check that one person is not lost outside the vertical crop.
Land on confidence
The final impression should come from posture, eye line and lighting. Large gestures are unnecessary for this scene direction.
What the studio currently accepts
- Source
- Two individual portraits, one performer per slot
- Upload
- JPG, PNG or WebP, up to 4 MB per photo
- Default scene length
- 10 seconds, 9:16 vertical
- Aspect ratios
- 9:16, 1:1, 16:9, 3:4, 4:3 and 21:9
- Length choices
- 10 or 15 seconds; your account balance is in credits and packages show the video time they cover
- Scene controls
- Fixed scene recipe; no custom prompt or motion-reference input
- Before submission
- Local photo preview, permission confirmation and displayed availability
Portraits supply identity references, not a motion recording
This effect starts from one person in each of two separate portraits. The video provider interprets the portrait references together with this studio’s scene recipe. Two-person scenes keep the references separate rather than requiring a collage. The flow does not upload a choreography video or let you direct frame-by-frame motion.
Recognizable likeness, coherent clothes and natural anatomy are requested, but they require review in the finished result. A pleasing opening frame cannot demonstrate that the rest of the clip is stable. Watch changes of angle, lighting and distance, plus any interaction between subjects and objects.
The scene’s rap or music-video styling describes a visual intention. A specific voice, song, melody, word-perfect verse or synchronized mouth movement is not guaranteed.
Where the scene can fit
A duo introduction
Use the paired staging as an opening visual for a creative duo, while clearly presenting the performance as AI-generated.
A vertical social post
The default 9:16 format suits a phone-screen composition; square and landscape choices are also available. Check safe space around faces before adding your own captions in an editor.
A mood-board moving image
Explore a warm lobby visual for a concept or presentation. A generated scene is a visual idea, not evidence that the subjects filmed in a real hotel.
Before you start
Use a source image and likenesses you have permission to submit. Choose your portraits and a 10- or 15-second duration. A 15-second video uses five more seconds from your balance than a 10-second video.
Packages add credits to your account, with the equivalent video time shown on each card. Combine the two clip lengths as you like; unused credits remain available. If your balance covers fewer than 10 seconds, add a package before starting another clip. Check an existing task before making another paid request if its response was uncertain.
Questions before you start
Does my source photo need a hotel background?
No. Use two clear portraits with readable faces and clothing. The scene recipe requests the lobby setting; the exact generated interior can vary.
Will each person sing a different verse?
The look suggests alternating performer attention. It does not guarantee words, a particular song, different recorded verses or synchronized mouth movement.
What is the video format?
This scene defaults to 10 seconds in 9:16. Choose 10 or 15 seconds; each clip uses the same number of video seconds from your balance.
MAKE YOUR SCENE